Define the frontier and track the acceleration.
Executable, expert-designed evaluations built from real work—so progress is measured where it matters.
Science Prediction Universe (SPU)
Science advances by prediction. Science Prediction Universe tests scientific reasoning against real experimental measurements across 100 public tasks and 16 private tasks.
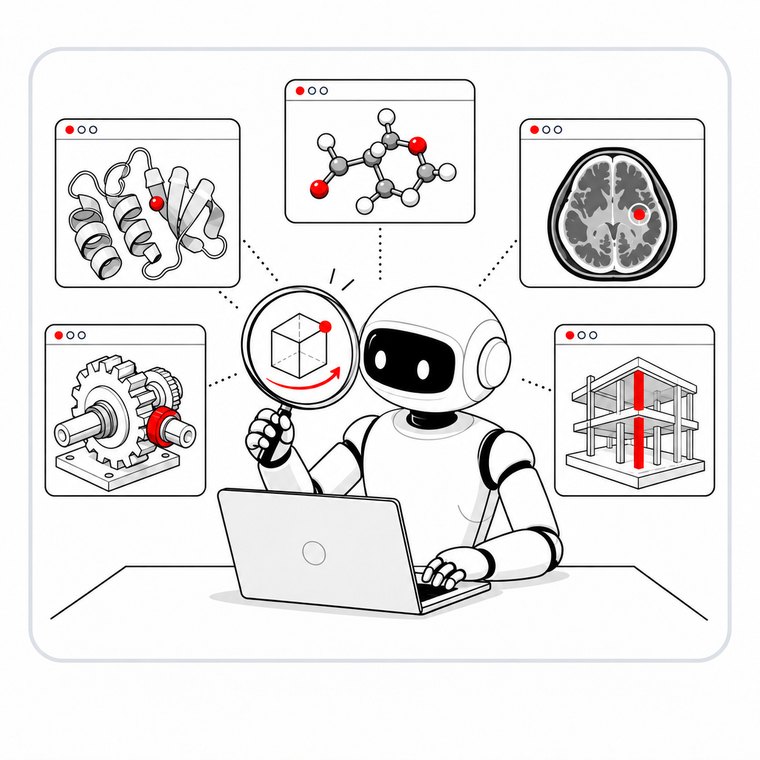
ScienceVision
250 expert questions across five scientific disciplines, testing whether models can obtain evidence from native 3D objects and reason from it.
PaperBenchX
93 paper-reproduction tasks across 12 research areas, scored through clean replay and evidence-backed scientific rubrics.
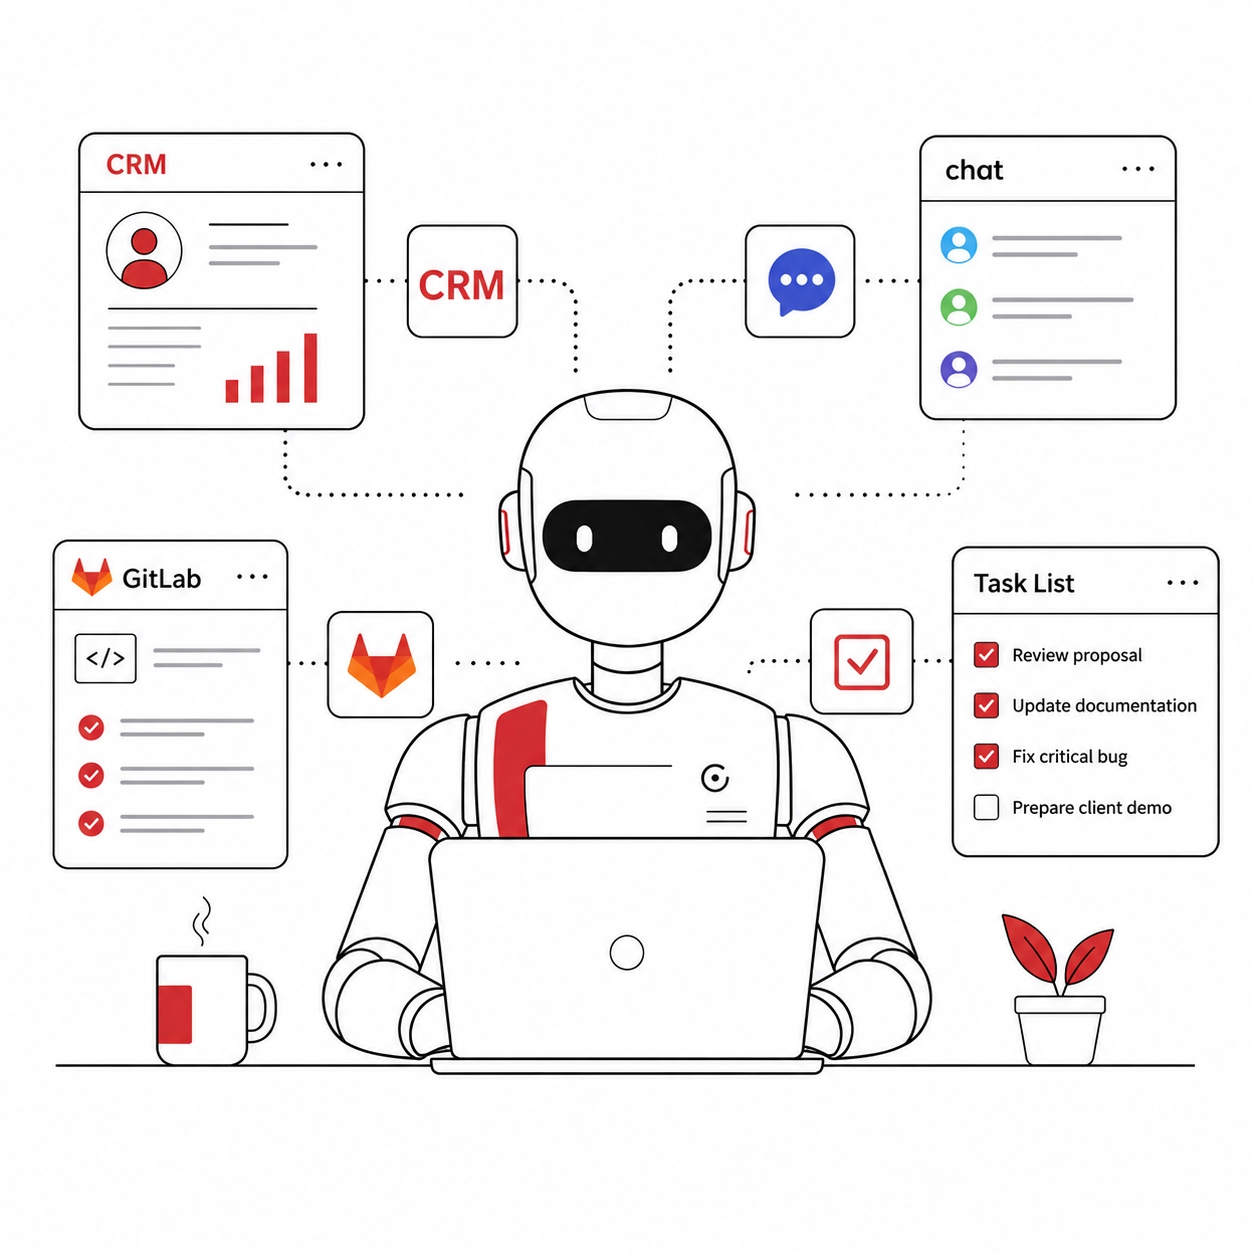
SaaS-Bench v1.1
v1.1 results across 106 tasks and 23 SaaS systems, comparing generic and native harnesses using Checkpoint Score and Resolved Score.
Monthly-SWEBench
A continuously updated benchmark evaluating AI coding agents on real-world software engineering tasks from GitHub issues.
RoadmapBench
115 real-world version-upgrade tasks from 17 repositories across 5 programming languages. Evaluates whether coding agents can implement substantial new functionality guided only by a multi-target specification.
EvoCode-Bench
26 multi-turn coding tasks with 227 evaluated rounds. Each task keeps the same workspace and agent session while requirements change, accumulate, and sometimes conflict.
ClawBench
Can AI browser agents complete everyday online tasks on live websites? ClawBench evaluates agents across V1/V2 tasks with isolated Chrome runs, request interception, five-layer traces, and agentic judging.
Echo Leaderboard
A dynamic evaluation engine for AI prediction systems, featuring multi-point aligned Elo ranking, three-track data collection, and adaptive scheduling across diverse domains including finance, politics, crypto, sports, and esports.
BabyVision
A benchmark for visual reasoning that challenges frontier MLLMs yet 3-year-olds can solve.